#17 LLM engineering and evals 5.5 min
Cut LLM Cost and Latency: Caching and Shorter Answers
Same six requests, over two minutes on a laptop. Add a cache and shorter answers, and watch the output tokens and the wait drop, with the real numbers on screen.
Show which requests hit the cache
Copy the code folder first. In cached.py add a print inside the loop that shows each question and whether it came from the cache (used == 0). Predict which of the six lines will say cache before you run python cached.py. This needs Ollama with llama3.2, as in the video.
A hint
The first three requests are the three different questions.
Repeat the traffic three times
In traffic.py change TRAFFIC to QUESTIONS * 3. Predict the number of requests and the number of cache hits that cached.py will print, and the output tokens if every uncached answer again reaches the 60 token cap. Then run it.
A hint
Count how many different questions there are.
Cap without asking for brevity
In concise.py remove the sentence 'Answer in one short sentence.' from the question but keep num_predict at 40, and print each answer. Predict how the answers end, then run it. Compare with what the video says about a cap on its own.
A hint
Add print(reply.message.content) inside the loop.
Combine both fixes
The video did not test the cache and the shorter answers together. Copy cached.py to both.py and make it send the short sentence and use a 40 token cap. Predict the number of cache hits, then run it and compare its tokens with the cached run and the concise run.
A hint
Put the same sentence in the cache key by changing the question before it is hashed.
These tasks are for you to try on your own machine. Nothing is checked or saved.
What this does not show
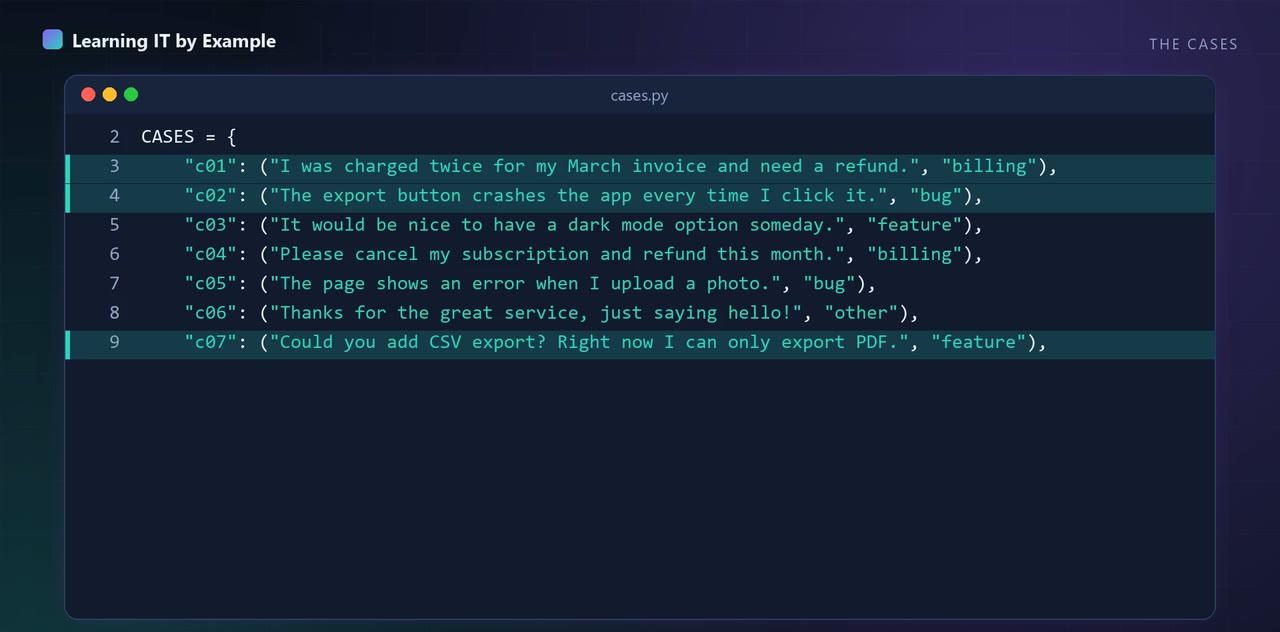
Six made-up requests (three questions, each asked twice) on one small local model, one run on one laptop. Tokens stand in for cost because a local model is free, so no bill was measured. The cache only helps exact repeats, shorter answers can lose detail, and the two fixes were not tested together. The two advice articles are vendor blog posts.
Up next in LLM engineering and evals
More in LLM engineering and evals
Related videos
- #11 Run an LLM Locally with Ollama and Python: First Call Local and open models
- #318 LLM Latency and Cost Budget: Which Lever Matters? Forward deployed engineer interviews
- #01 Local AI Agent in Python: No API Key (Ollama) AI agents and MCP
- #02 RAG From Scratch in Python: Chunk, Embed, Retrieve (Local) RAG and vector search