#05 LLM engineering and evals 5.7 min
Structured Outputs in Python: Valid JSON Is Not Correct JSON
Turn messy emails into structured tickets with a local model and Pydantic, then test the answers. Valid JSON is not the same as correct JSON.
Add an eighth test case
Copy the code folder first. In emails.py add one more tuple to CASES: a support email you invent, with the category and urgency you think are right. Predict the last line that run_tests.py will print, then run it. Did your new case pass? Pick wording that clearly fits one category.
A hint
The last line uses len(CASES), so it counts your new case on its own.
Change what you expect, not the code
In emails.py change the expected category of the slow phone email from bug to feature. The temperature is zero and the seed is fixed, so predict what happens to that line and to the final score. Run the tests. What does this tell you about who decides what is correct?
A hint
The tests only compare the model with the labels you wrote down. They cannot tell you which label is right.
Make Pydantic reject an answer
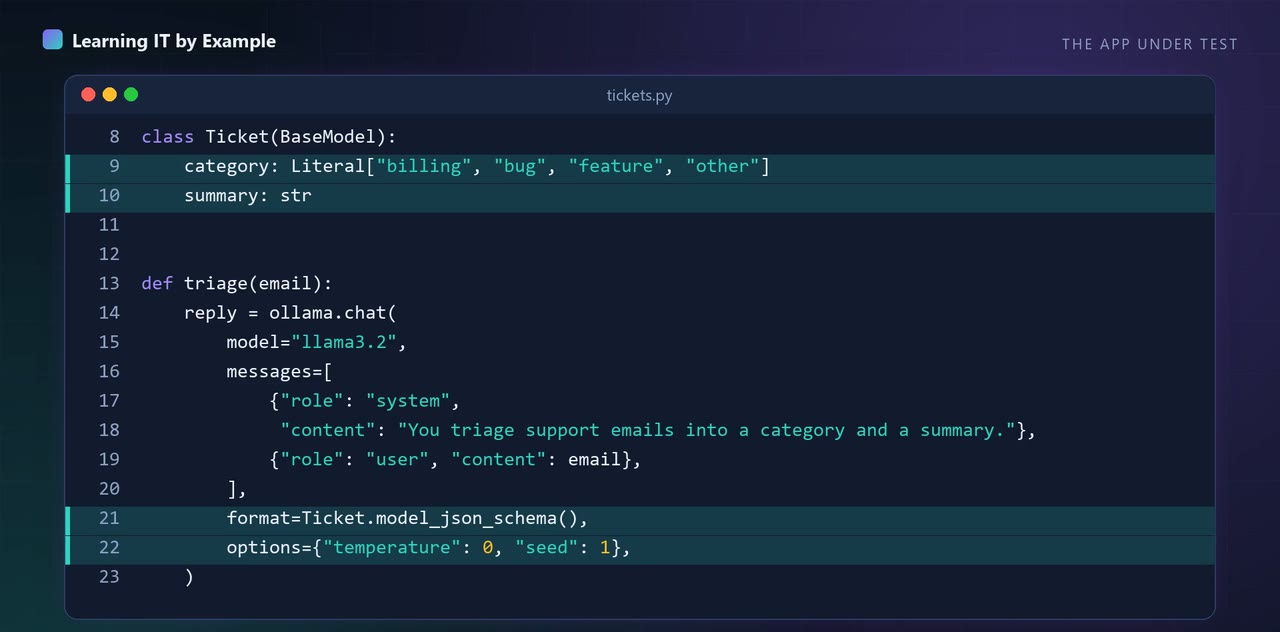
Open a Python prompt in the folder and import Ticket from tickets. Call Ticket.model_validate_json with the text {"category": "refund", "urgency": "high", "summary": "x"}. Predict whether it succeeds, then run it and read the error. Try again with the category set to billing.
A hint
Look at the Literal lists in the Ticket class. Only the listed words are allowed for category and urgency.
Add a fifth category
In tickets.py add the word question to the category list in the Ticket class. In emails.py change the expected category of the password email from other to question. Predict whether the model will now choose question for that email and whether the score changes, then run the tests. Compare with the video, where it was labelled billing.
A hint
A schema limits the allowed values. It does not force the model to pick any particular one.
These tasks are for you to try on your own machine. Nothing is checked or saved.
What this does not show
Seven made-up emails with labels chosen by the author, one small local model (llama3.2), one run at temperature 0. The 5 of 7 score says nothing about your data or another model. A schema constrains the shape, not the truth of the answer.
Up next in LLM engineering and evals
More in LLM engineering and evals
Related videos
- #26 Plan, Act, Reflect: Does It Help a Small Model? AI agents and MCP
- #58 JSON Mode vs Schema vs Function Calling: Measured (Ollama) LLM engineering and evals
- #63 Few-Shot Examples: How Many Is Enough? A Measured Test LLM engineering and evals
- #64 Chain of Thought: When Step by Step Helps, and Its Cost LLM engineering and evals