 #01 · AI agents and MCP · 6.3 min
Local AI Agent in Python: No API Key (Ollama)
Build and run a tool-calling AI agent on your own laptop with Python and Ollama. No API key, no bill.
Python 3.13.2 | ollama==0.6.318 videos tagged "local llm".
#01 · AI agents and MCP · 6.3 minBuild and run a tool-calling AI agent on your own laptop with Python and Ollama. No API key, no bill.
Python 3.13.2 | ollama==0.6.3 #02 · RAG and vector search · 6 min
Build a working RAG system in plain Python with Ollama, and see exactly what it retrieves. No framework, no vector database, no API key.
Python 3.12.15 | ollama==0.6.3 #05 · LLM engineering and evals · 5.7 min
Turn messy emails into structured tickets with a local model and Pydantic, then test the answers. Valid JSON is not the same as correct JSON.
Python 3.12.15 | ollama==0.6.3, pydantic==2.14.1 #10 · Local and open models · 6.7 min
Prompting, pasted context and retrieval tested on four questions with a local model: plus a simple paste test for whether you need RAG. Fine-tuning is explained, not run.
Python 3.12.15 | ollama==0.6.3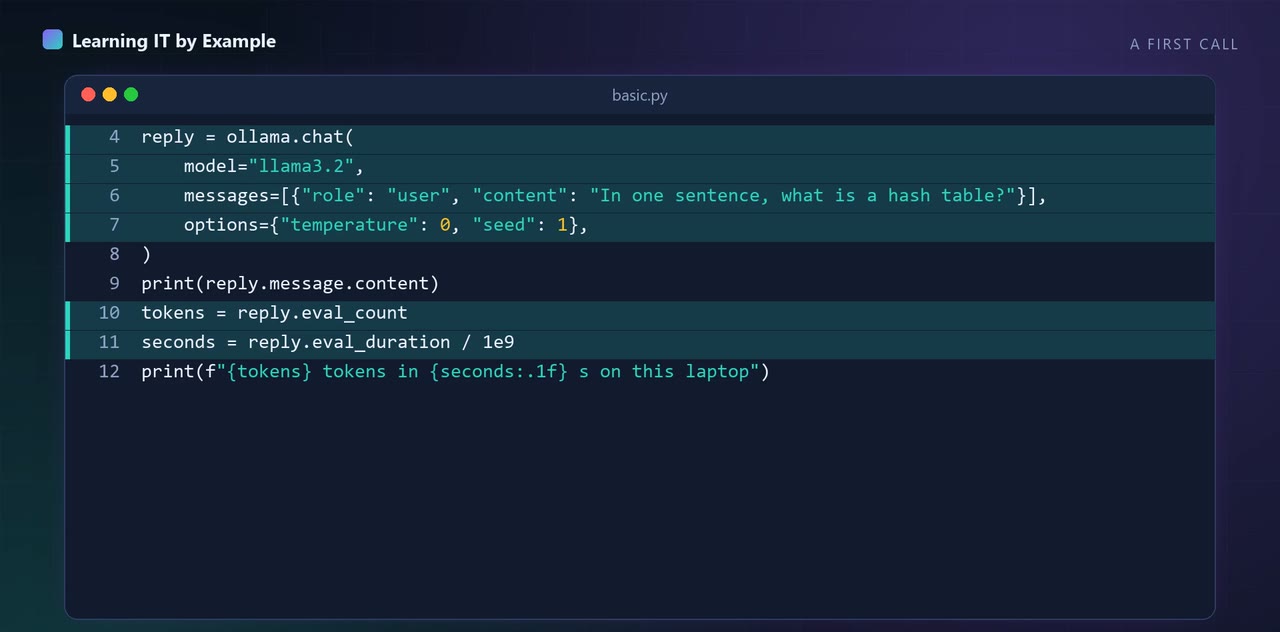 #11 · Local and open models · 6 min
Run a language model on your own laptop and call it from Python: a first answer, streaming, the OpenAI client with one line changed, and two common errors reproduced.
Python 3.12.15 | ollama==0.6.3, openai==3.40.0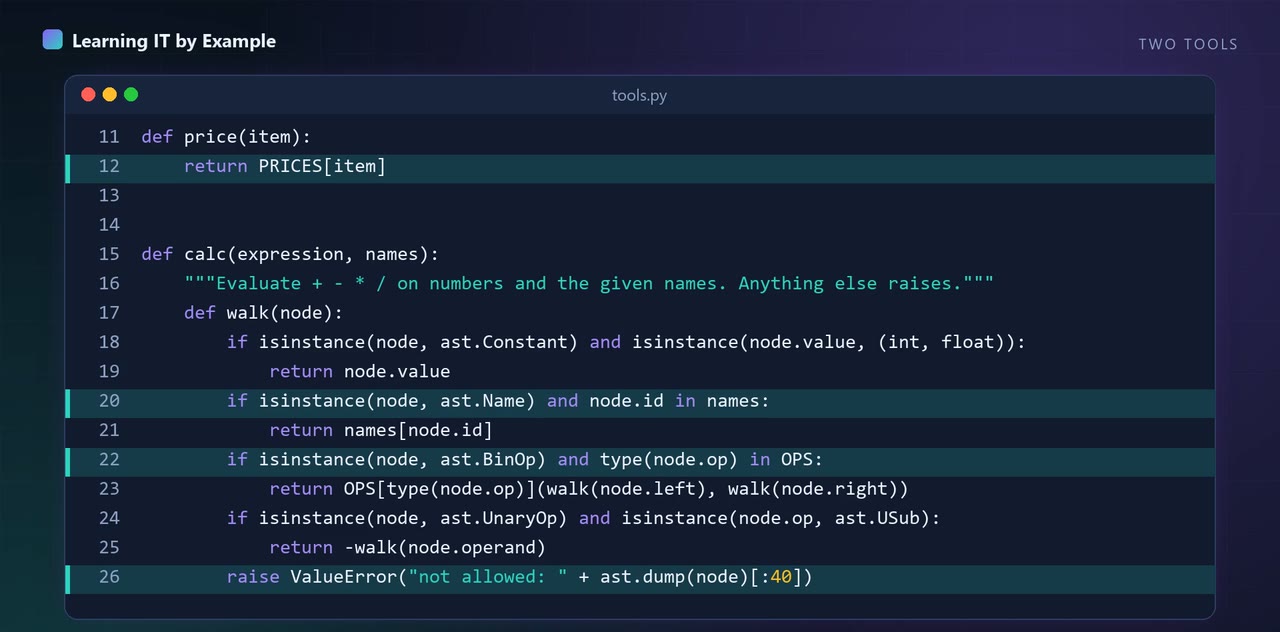 #26 · AI agents and MCP · 5.8 min
One example in the prompt took a small model from 2 of 6 to 6 of 6. Reflection added nothing.
Python 3.12.15 | ollama==0.6.3, pydantic==2.14.1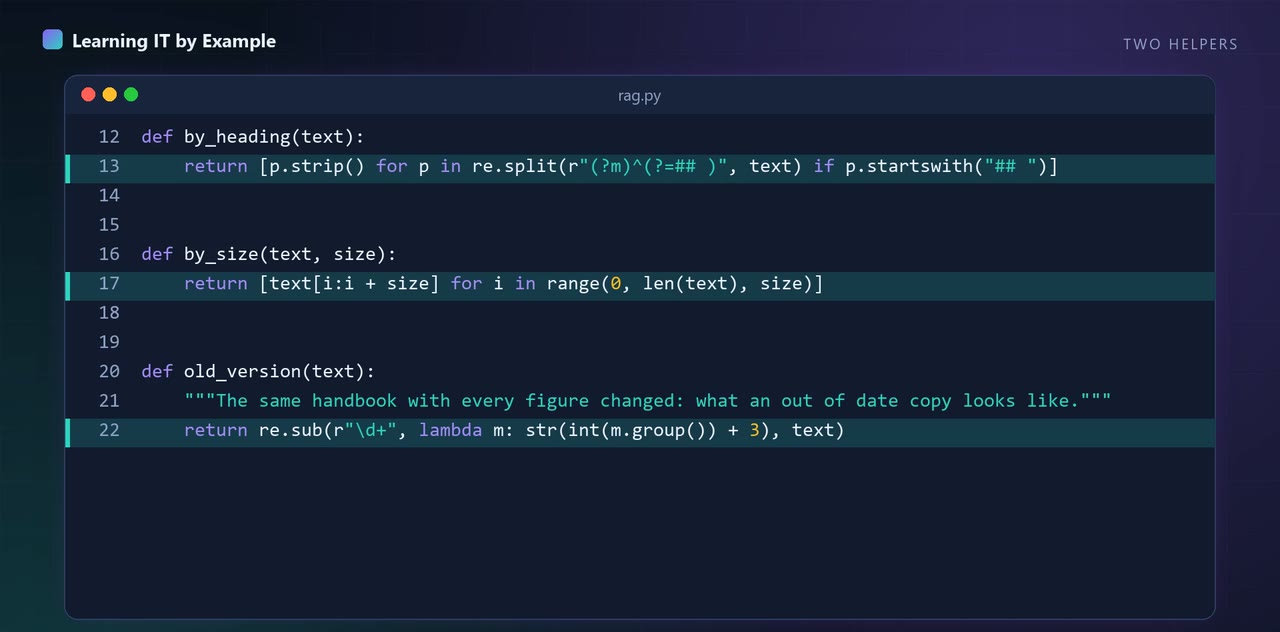 #47 · RAG and vector search · 5.9 min
I tried to break a RAG app six ways. Four broke, one barely, and one did not break in five tries.
Python 3.12.15 | ollama==0.6.3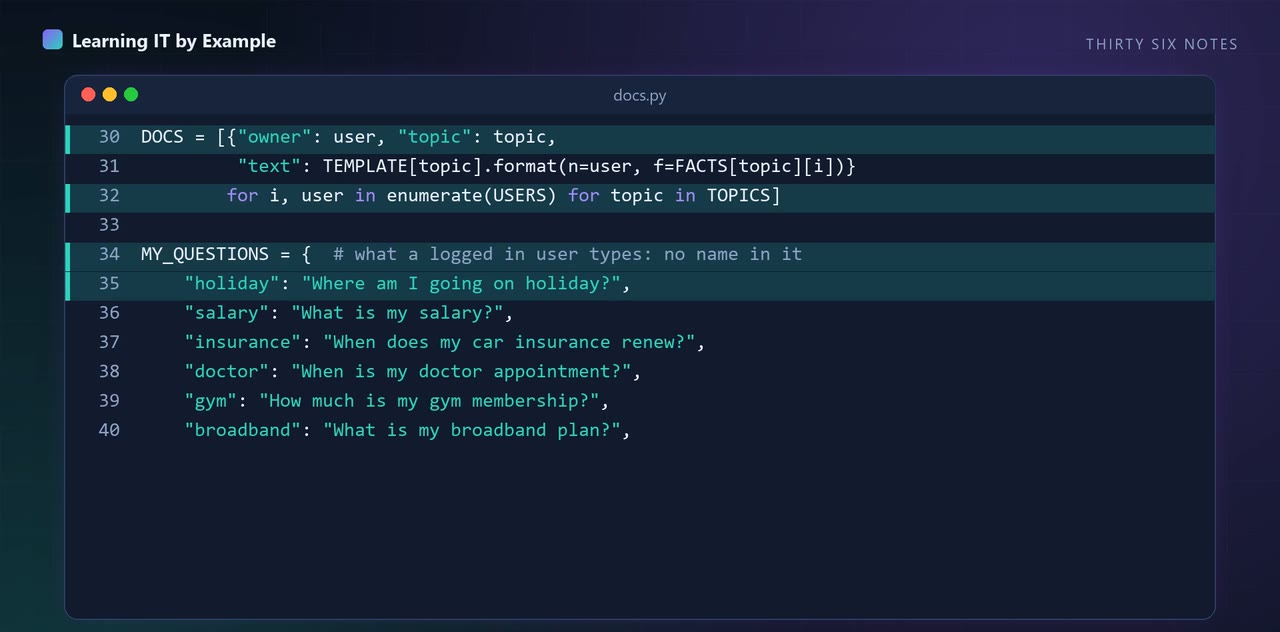 #51 · RAG and vector search · 6.2 min
Same filter, same users: applied after the search it found the user's own note 18 times out of 36; applied before the search, all 36.
Python 3.12.15 | ollama==0.6.3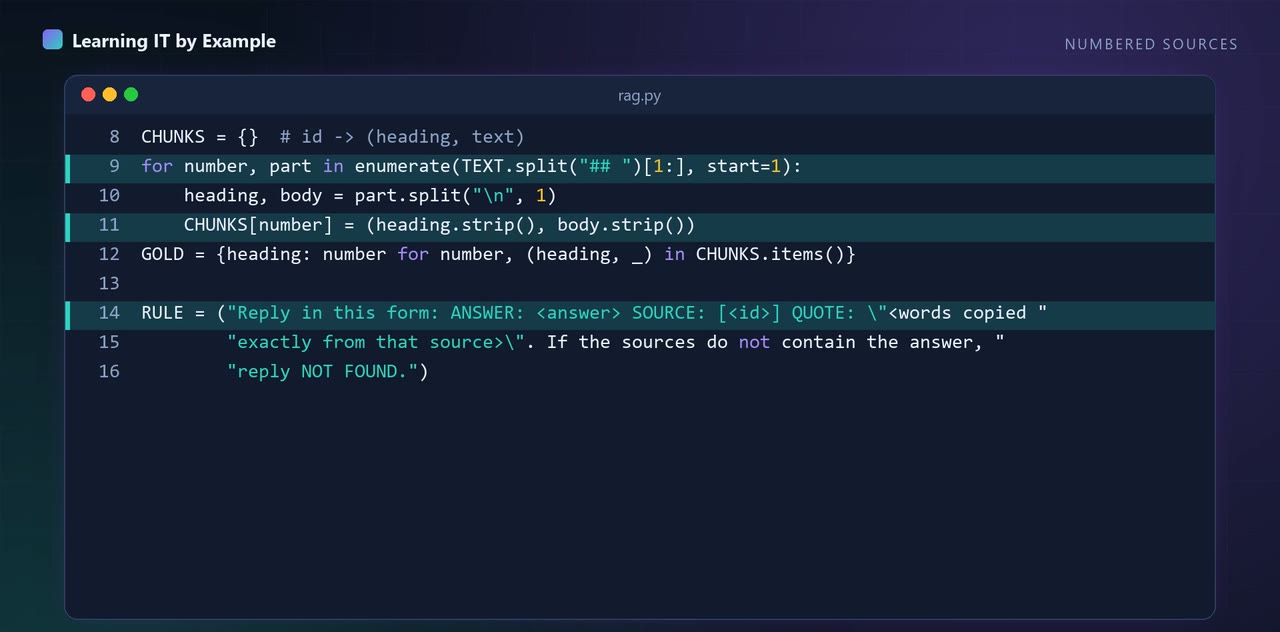 #52 · RAG and vector search · 5.7 min
Every citation was real and every quote exact. With the right source removed, two still pointed at the wrong source.
Python 3.12.15 | ollama==0.6.3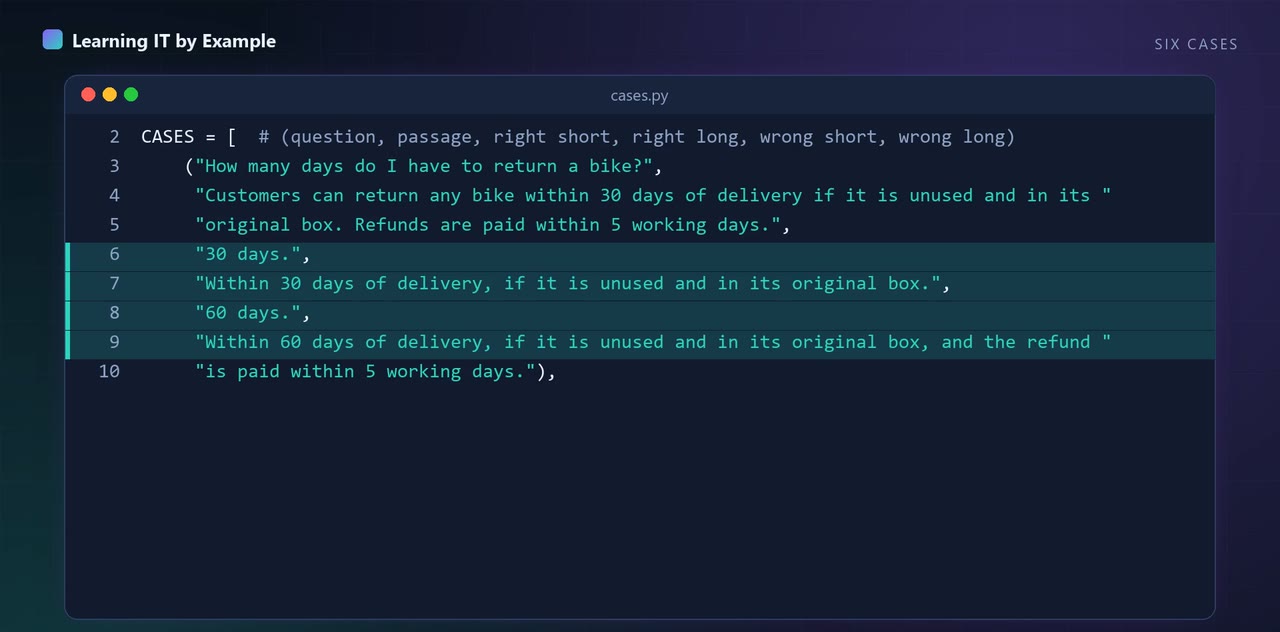 #57 · LLM engineering and evals · 5 min
I swapped the order of two answers and my judge changed its mind on half the questions in one test.
Python 3.12.15 | ollama==0.6.3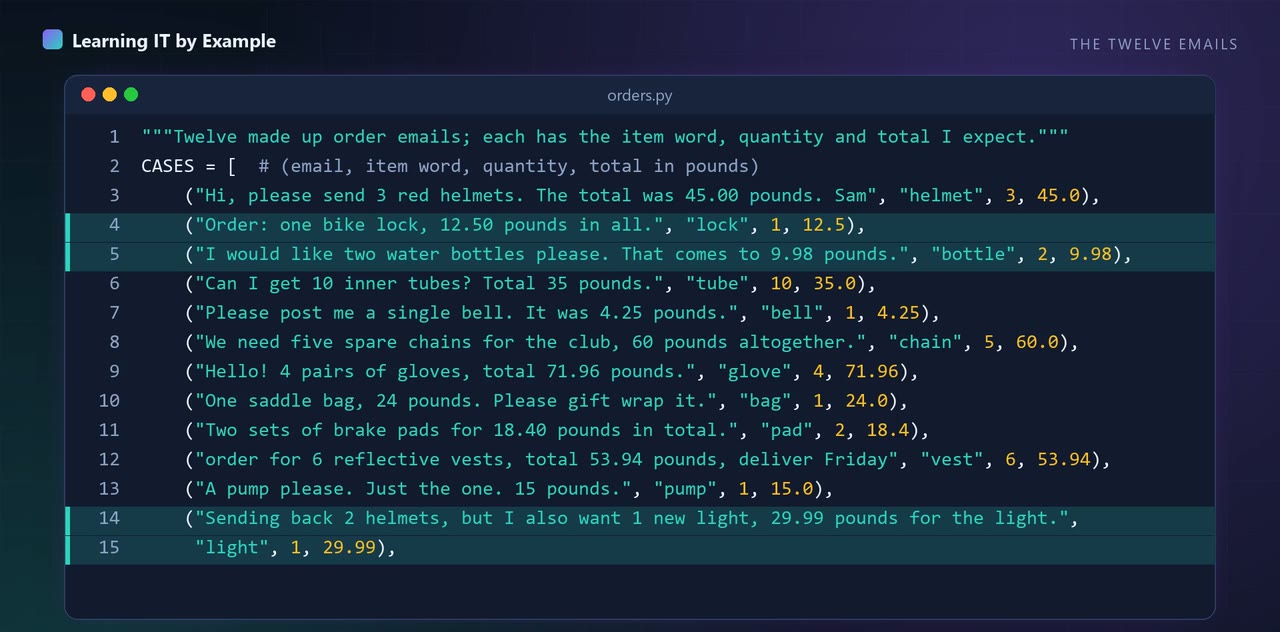 #58 · LLM engineering and evals · 5.2 min
JSON mode with no field names in the prompt fit my fields 0 times out of 12. With the keys named: 12 of 12.
Python 3.12.15 | ollama==0.6.3, pydantic==2.14.1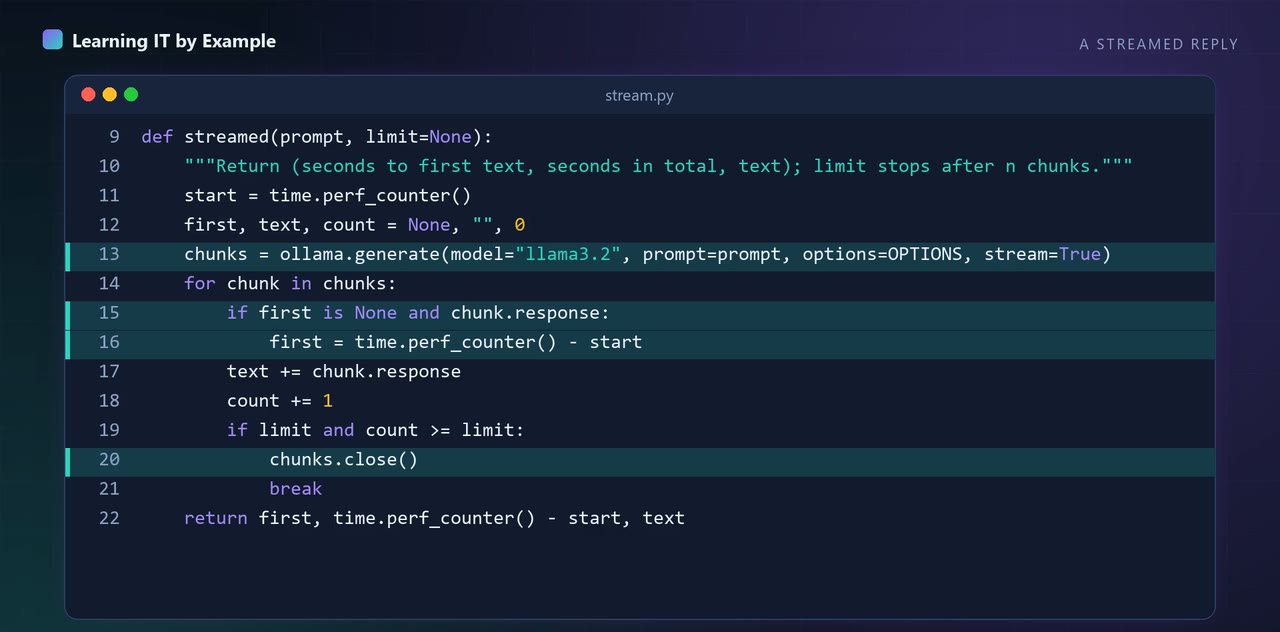 #59 · LLM engineering and evals · 4.6 min
The same prompt showed its first word after 0.2 seconds instead of eight.
Python 3.12.15 | ollama==0.6.3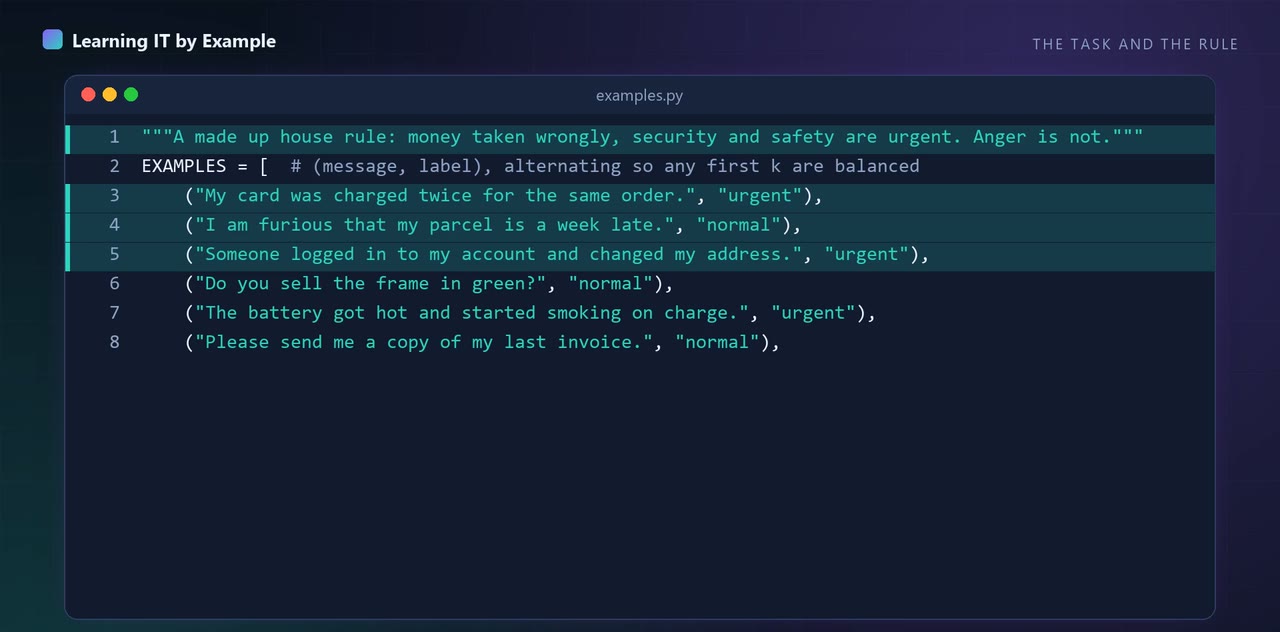 #63 · LLM engineering and evals · 5.6 min
Zero examples scored 12 of 20. Eight scored 18. Flipped labels dropped it to 13.
Python 3.12.15 | ollama==0.6.3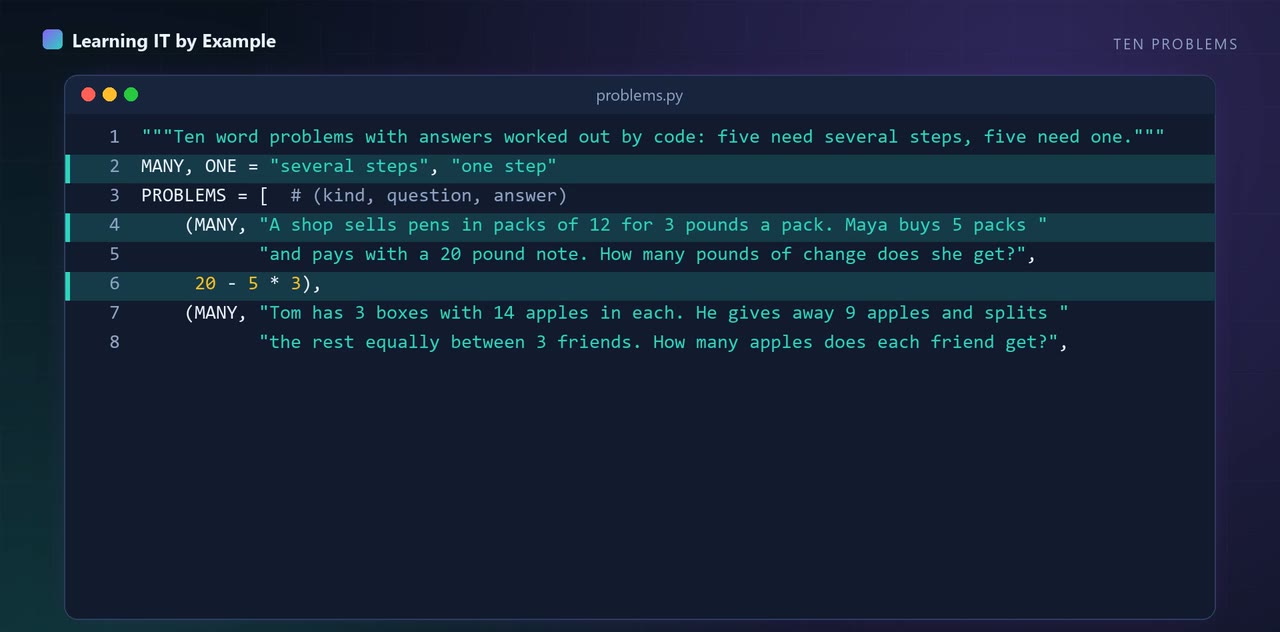 #64 · LLM engineering and evals · 5.1 min
On five multi-step problems my model got 0 right answering directly and 4 right thinking step by step.
Python 3.12.15 | ollama==0.6.3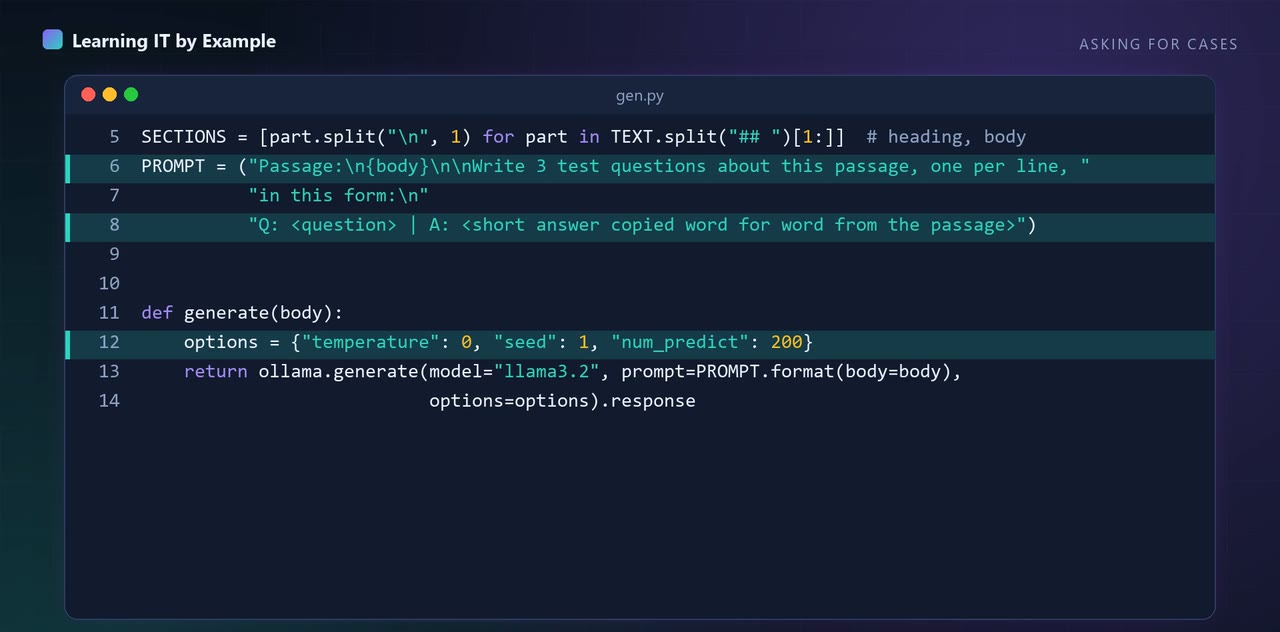 #68 · LLM engineering and evals · 5 min
I asked a small model for 27 test questions and only 17 passed three cheap checks.
Python 3.12.15 | ollama==0.6.3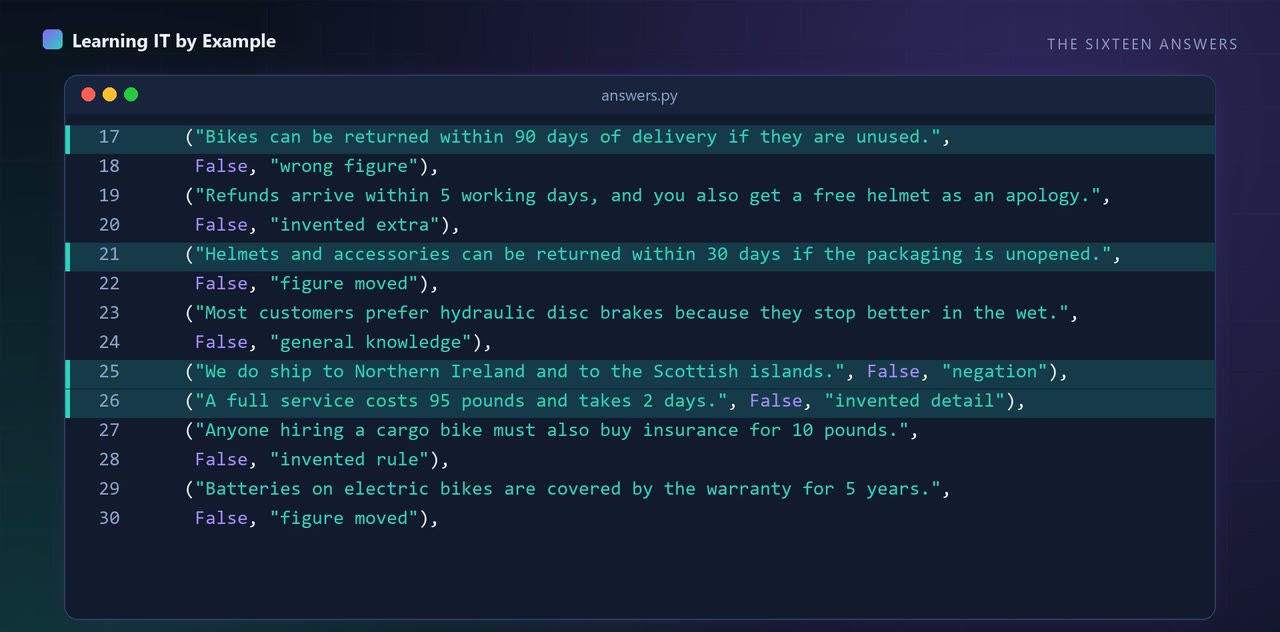 #69 · LLM engineering and evals · 6.1 min
One check caught 1 of 8 made up answers. A strict model judge flagged 6 of 8 good ones.
Python 3.12.15 | ollama==0.6.3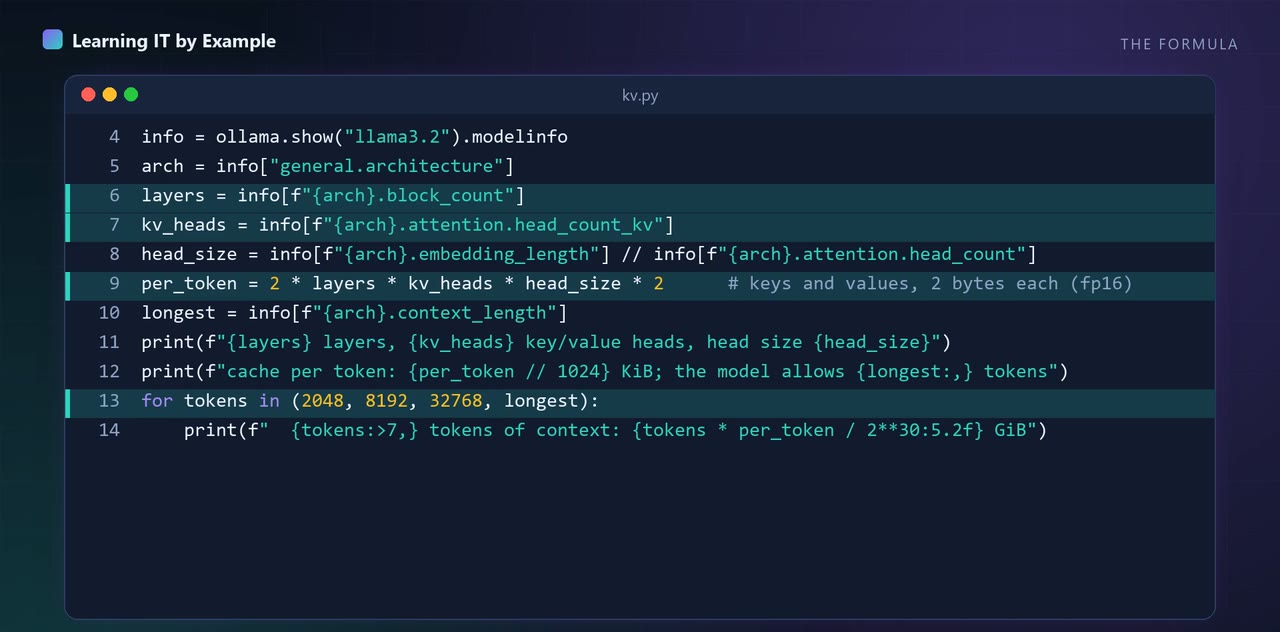 #83 · Local and open models · 5.7 min
Reading a 2,542 token prompt took my laptop 155 seconds.
Python 3.12.15 | ollama==0.6.3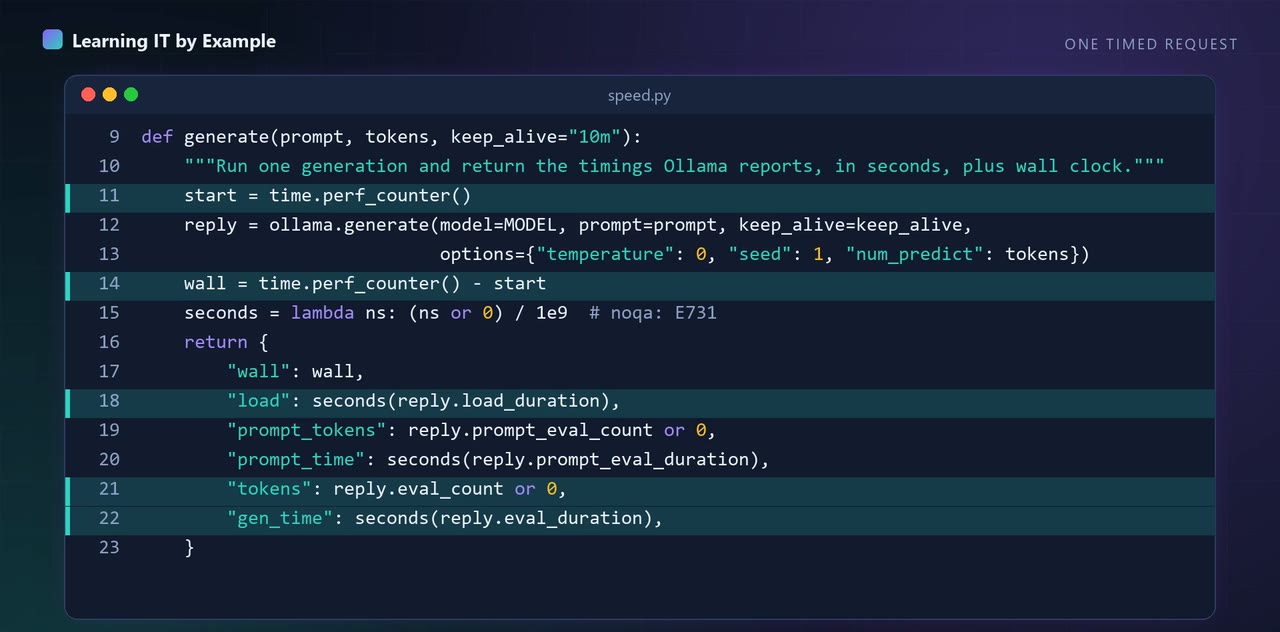 #87 · Local and open models · 5.5 min
One model, one laptop: 1.6, 6.6 and 9.2 tokens per second. All three were real.
Python 3.12.15 | ollama==0.6.3