 #17 · LLM engineering and evals · 5.5 min
Cut LLM Cost and Latency: Caching and Shorter Answers
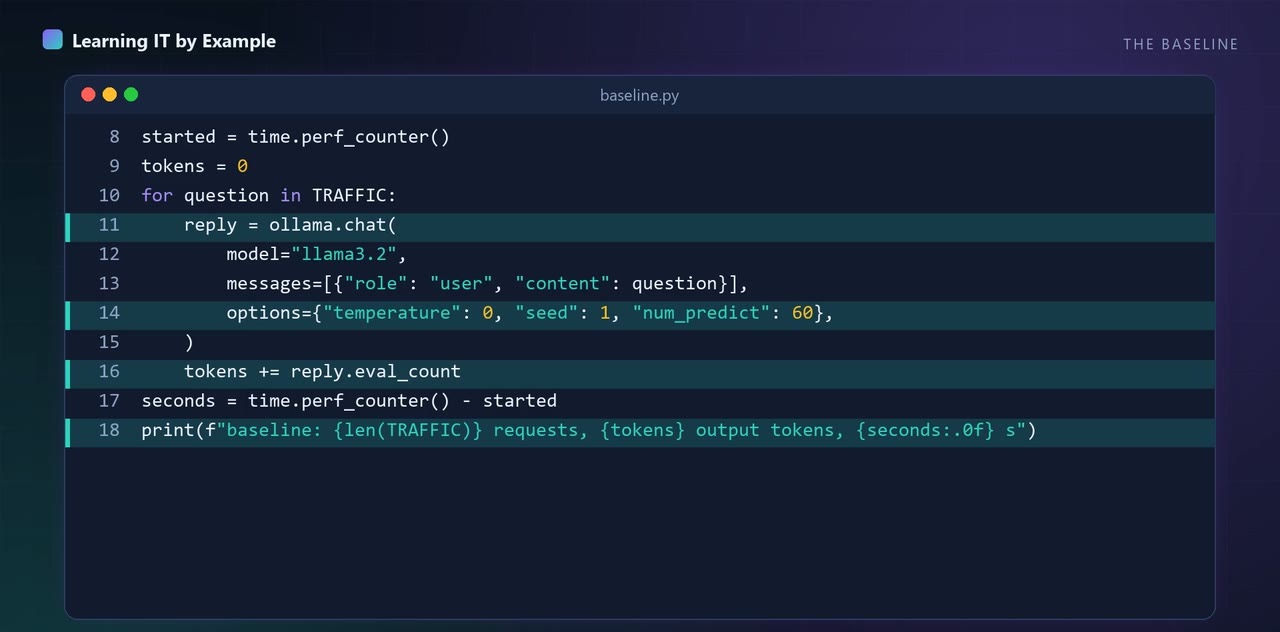
Same six requests, over two minutes on a laptop. Add a cache and shorter answers, and watch the output tokens and the wait drop, with the real numbers on screen.
Python 3.12.15 | ollama==0.6.3