#204 Data governance 6.1 min
Tag PII Columns in Python, Including a False Positive
A 25-line PII scanner tagged email, phone and postcode right, and order references wrong.
Lower the share needed
Copy the code folder first. In detect.py change 0.6 to 0.2 in the tag function and run python run.py. You should see the notes line change to pii: email (25%), because 1 of 4 values is 25 percent. Say in a sentence whether this is a better or worse scanner, and why.
A hint
The video says too low a share flags everything, and too high misses real data.
Add a column with a name hint
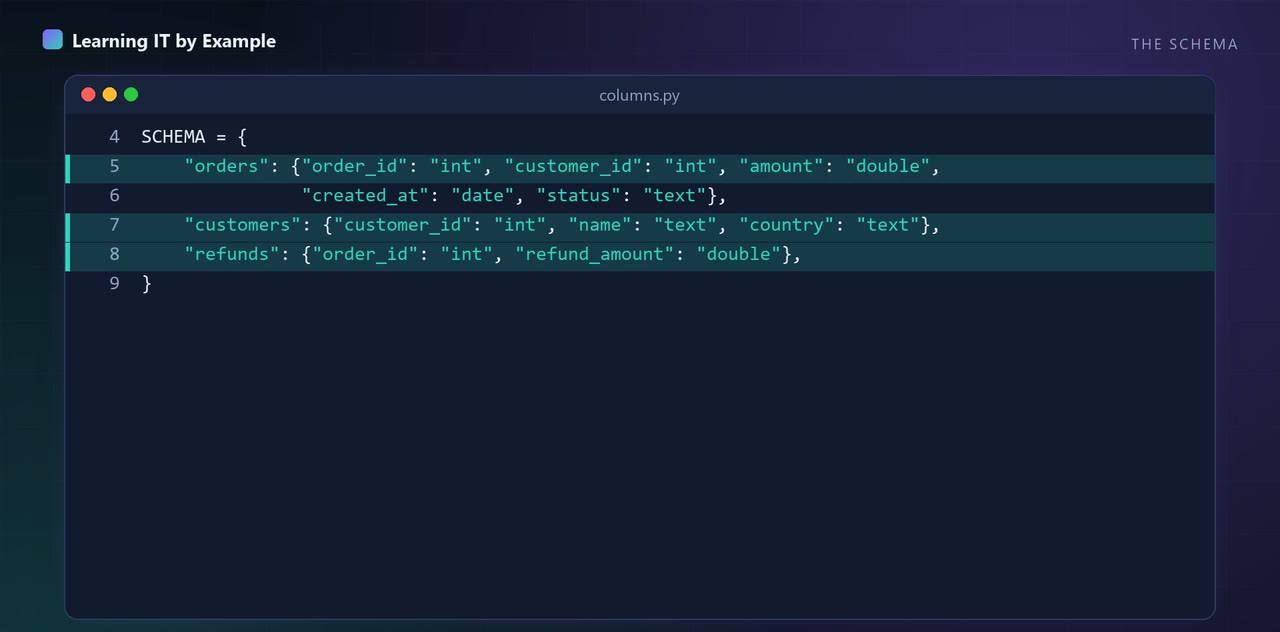
In sample.py add a new column after total: "dob": ["1990-01-02", "1985-05-06", "", "1992-07-08", "1979-11-12", "2000-03-04"]. Run python run.py. You should see dob tagged pii: by column name, because none of the patterns match the values but the name has a hint.
A hint
The name hints are name, birth and dob.
Change the order references
In sample.py change each ref value to start with 5 instead of 07, for example 51200000001, 51200000002 and so on up to 51200000006. Run python run.py. You should see ref become no match. Then explain in one sentence why this changes the data, not the scanner.
A hint
The phone pattern needs a +44 or a 0 at the start.
Plant a National Insurance number column
In sample.py add a column called payroll with six values, each in the form QQ123456C but with different digits, for example QQ123456C, QQ234567A and so on. Predict which tag you will get before you run python run.py, and then check.
A hint
The NI pattern is two letters, six digits, and a letter from A to D.
These tasks are for you to try on your own machine. Nothing is checked or saved.
What this does not show
Made-up table of six rows; the patterns and the 60 percent line are my choices, and names or addresses in free text are missed.